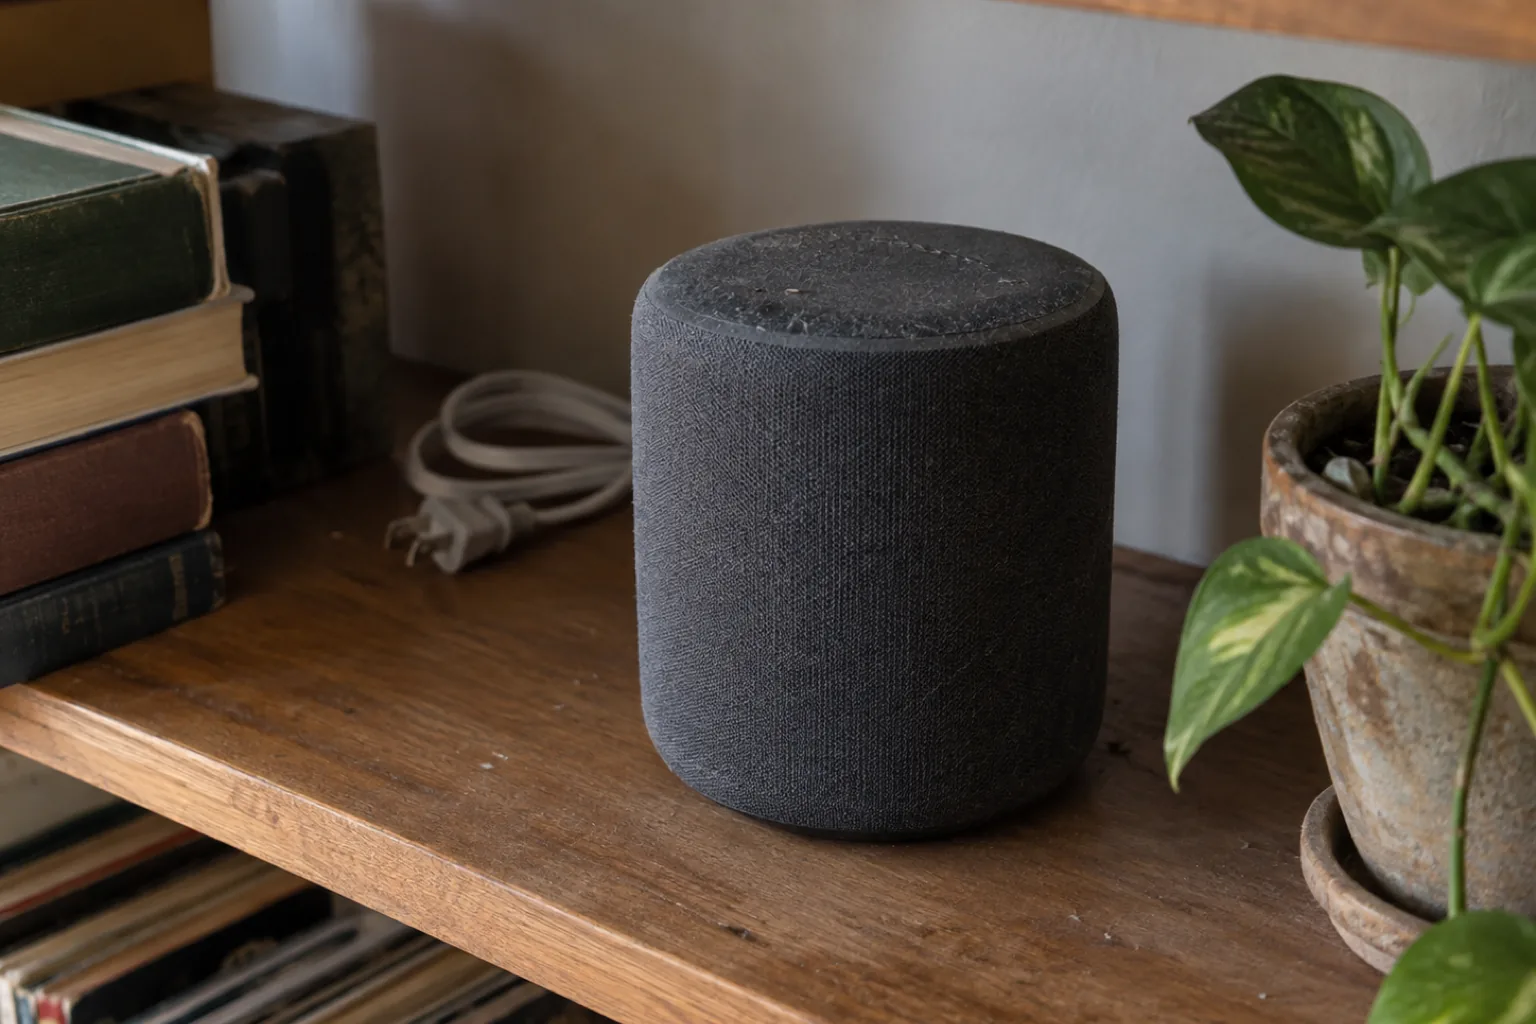
There is a cylinder on a shelf in a lot of houses, about the size of a coffee tin, fabric-covered, with a ring of light around the top. It was bought with some enthusiasm somewhere between 2016 and 2019. It is now used for two things: timers and music.
That object is the correct starting point for thinking about what OpenAI demonstrated on Monday, because it is what happened last time.
The company showed a model called GPT-4o on Monday that handles speech directly, responds in an average of about 320 milliseconds, and can be interrupted mid-sentence. Setting that beside the previous generation of voice assistants is the useful exercise, because the two are attempting the same thing and failing at different points.
The first system, and where it broke
The 2011 generation worked by pipeline. Speech went to a recognizer that turned it into text. The text went to an intent classifier that decided which of a fixed set of things you wanted. That produced a response, which was handed to a speech synthesizer.
Three separate systems, each with its own error rate, arranged in series. Errors did not average out; they compounded, because a misrecognized word produces a misclassified intent produces a confidently wrong answer.
But the fatal problem was not accuracy. It was the fixed set of things. An intent classifier can only route to an intent somebody implemented, so the system’s competence had a hard edge, and users found the edge within about a week. What they did next is the whole story: they stopped trying. Timers and music are the two intents that always worked.
That is why the cylinder is on the shelf. Not because it failed, but because it succeeded at a small number of things and people correctly narrowed their use to those.
The second system, and where it is different
The new arrangement is not a pipeline. One model takes audio in and produces audio out, without the intermediate text stage as a separate system with its own failure mode.
That has two consequences. The first is latency: a pipeline’s response time is the sum of its stages, and removing stages removes their contributions. Responding inside the interval a person expects is not a polish improvement. It is the difference between a conversation and a transaction, and it is the thing every previous system got wrong.
The second is that there is no fixed set of intents. The system is not routing to implemented functions; it is generating a response. The hard edge is gone.
Which means the two systems fail in opposite directions. The old one said it did not understand. The new one will always have something to say, and whether the thing is true is a separate question the architecture does not address.
What the difference teaches
The lesson is about which constraint was binding, and almost everybody got it wrong the first time.
Through the 2010s the assumed constraint was recognition accuracy. Enormous effort went into word error rates, and word error rates came down a great deal, and the assistants did not become meaningfully more useful. That should have been informative and mostly was not.
The binding constraint was the fixed intent set, and no amount of better hearing addresses it. A system that perfectly recognizes a request it has no implementation for is exactly as useless as one that mishears it.
Removing the intent set is therefore the actual advance here, and it is the part getting the least attention, because it is invisible in a demonstration. What a demonstration shows is the latency and the interruption handling, which are the parts you can film.
Why the latency figure is the one to hold onto
An average of about 320 milliseconds sounds like an engineering detail and is the closest thing in the announcement to a claim about what the product is.
Ordinary conversational turn-taking happens on roughly that scale. The gap between one person stopping and the next starting is a few hundred milliseconds across languages and cultures, and it is remarkably consistent, which means people are not waiting for a sentence to finish before preparing a reply. They are predicting.
A system that responds inside that window is inside the interval where a person is not yet waiting. Outside it, even by half a second, the exchange stops feeling like conversation and starts feeling like a query returning a result, which is what every previous system felt like and is why people spoke to them in commands rather than in sentences.
What has not changed
Two things, and they are the two that put the cylinder on the shelf.
Reliability of action. Answering a question is one capability; doing something in the world is another, and the second requires integrations with calendars, payments, home systems and everything else, each of which has to be built, permissioned and maintained. Nothing about the model architecture makes that easier.
And trust after a failure. The reason people narrowed to timers and music is that a wrong answer once costs the system a whole category of use permanently. A system that is right most of the time, on things a person cannot easily check, is in a worse position than one that fails visibly, because the user has no way to know which mode they are in.
A third thing is unchanged and is the hardest: knowing when to stop talking. The failure mode of a system that always has a response is that it responds when it should decline, and a spoken interface makes that worse, because a wrong answer delivered in a fluent voice carries confidence the text version does not.
What to watch
Not the demonstrations, which will be impressive, and not the benchmark numbers, which measure the part that was never the constraint.
Watch for what people use it for after three months. The useful measurement is not whether somebody tries it; it is whether the set of things they ask it narrows the way it narrowed last time. If in September the dominant uses are the conversational equivalent of timers and music, the intent set will have been replaced by a self-imposed one and the outcome will be the same.
Then there are the integrations, which is where this actually gets decided. A voice interface that can talk about anything and act on almost nothing is a better version of the thing on the shelf. The moment worth noticing is the first time one of these reliably completes a task with consequences, because that is when somebody has to decide what it may do without asking.